Web Scraping Without the Maintenance
Pull structured data from any website with a real browser — then schedule it, route it into a spreadsheet, and watch the recording when something changes.
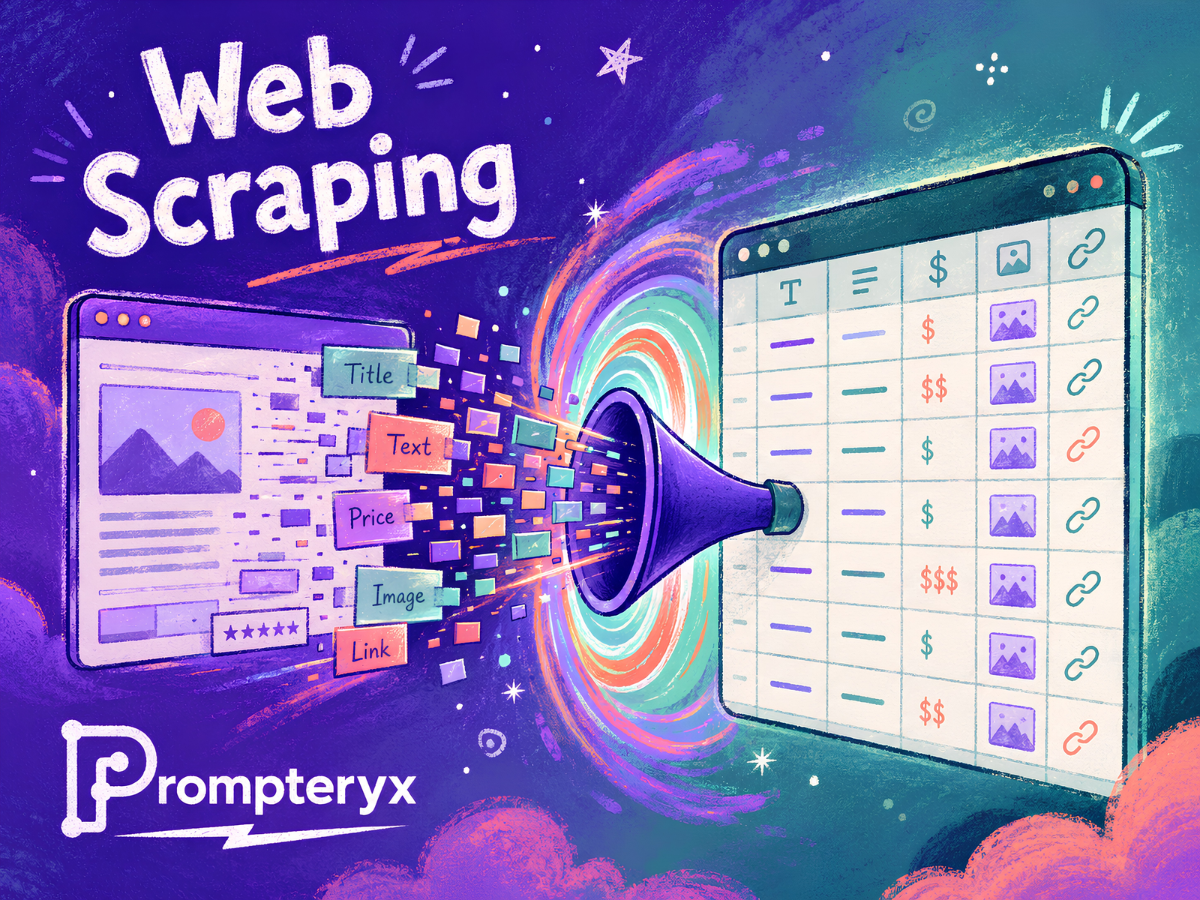
Most scraping breaks for two reasons: the target site renders with JavaScript, and your selectors snap the moment the layout shifts. Prompteryx runs a real Chromium browser so JavaScript, lazy-loading and logins all work, and every element you target is captured with several ranked fallback selectors — if the primary one breaks, the next one takes over automatically before any AI is involved.
You build the scraper visually (or record yourself doing it once), schedule it to run on its own, and send the results wherever they need to go across 3,000+ connected apps. Every run is recorded as video, so when a site changes you can see exactly what happened instead of guessing.
The problem
DIY scrapers and API-only tools are brittle and high-maintenance. Pure HTTP scrapers can't see JavaScript-rendered content; single-selector tools fail silently the next time a class name changes; and most need an engineer on standby to keep them alive.
How it works in Prompteryx
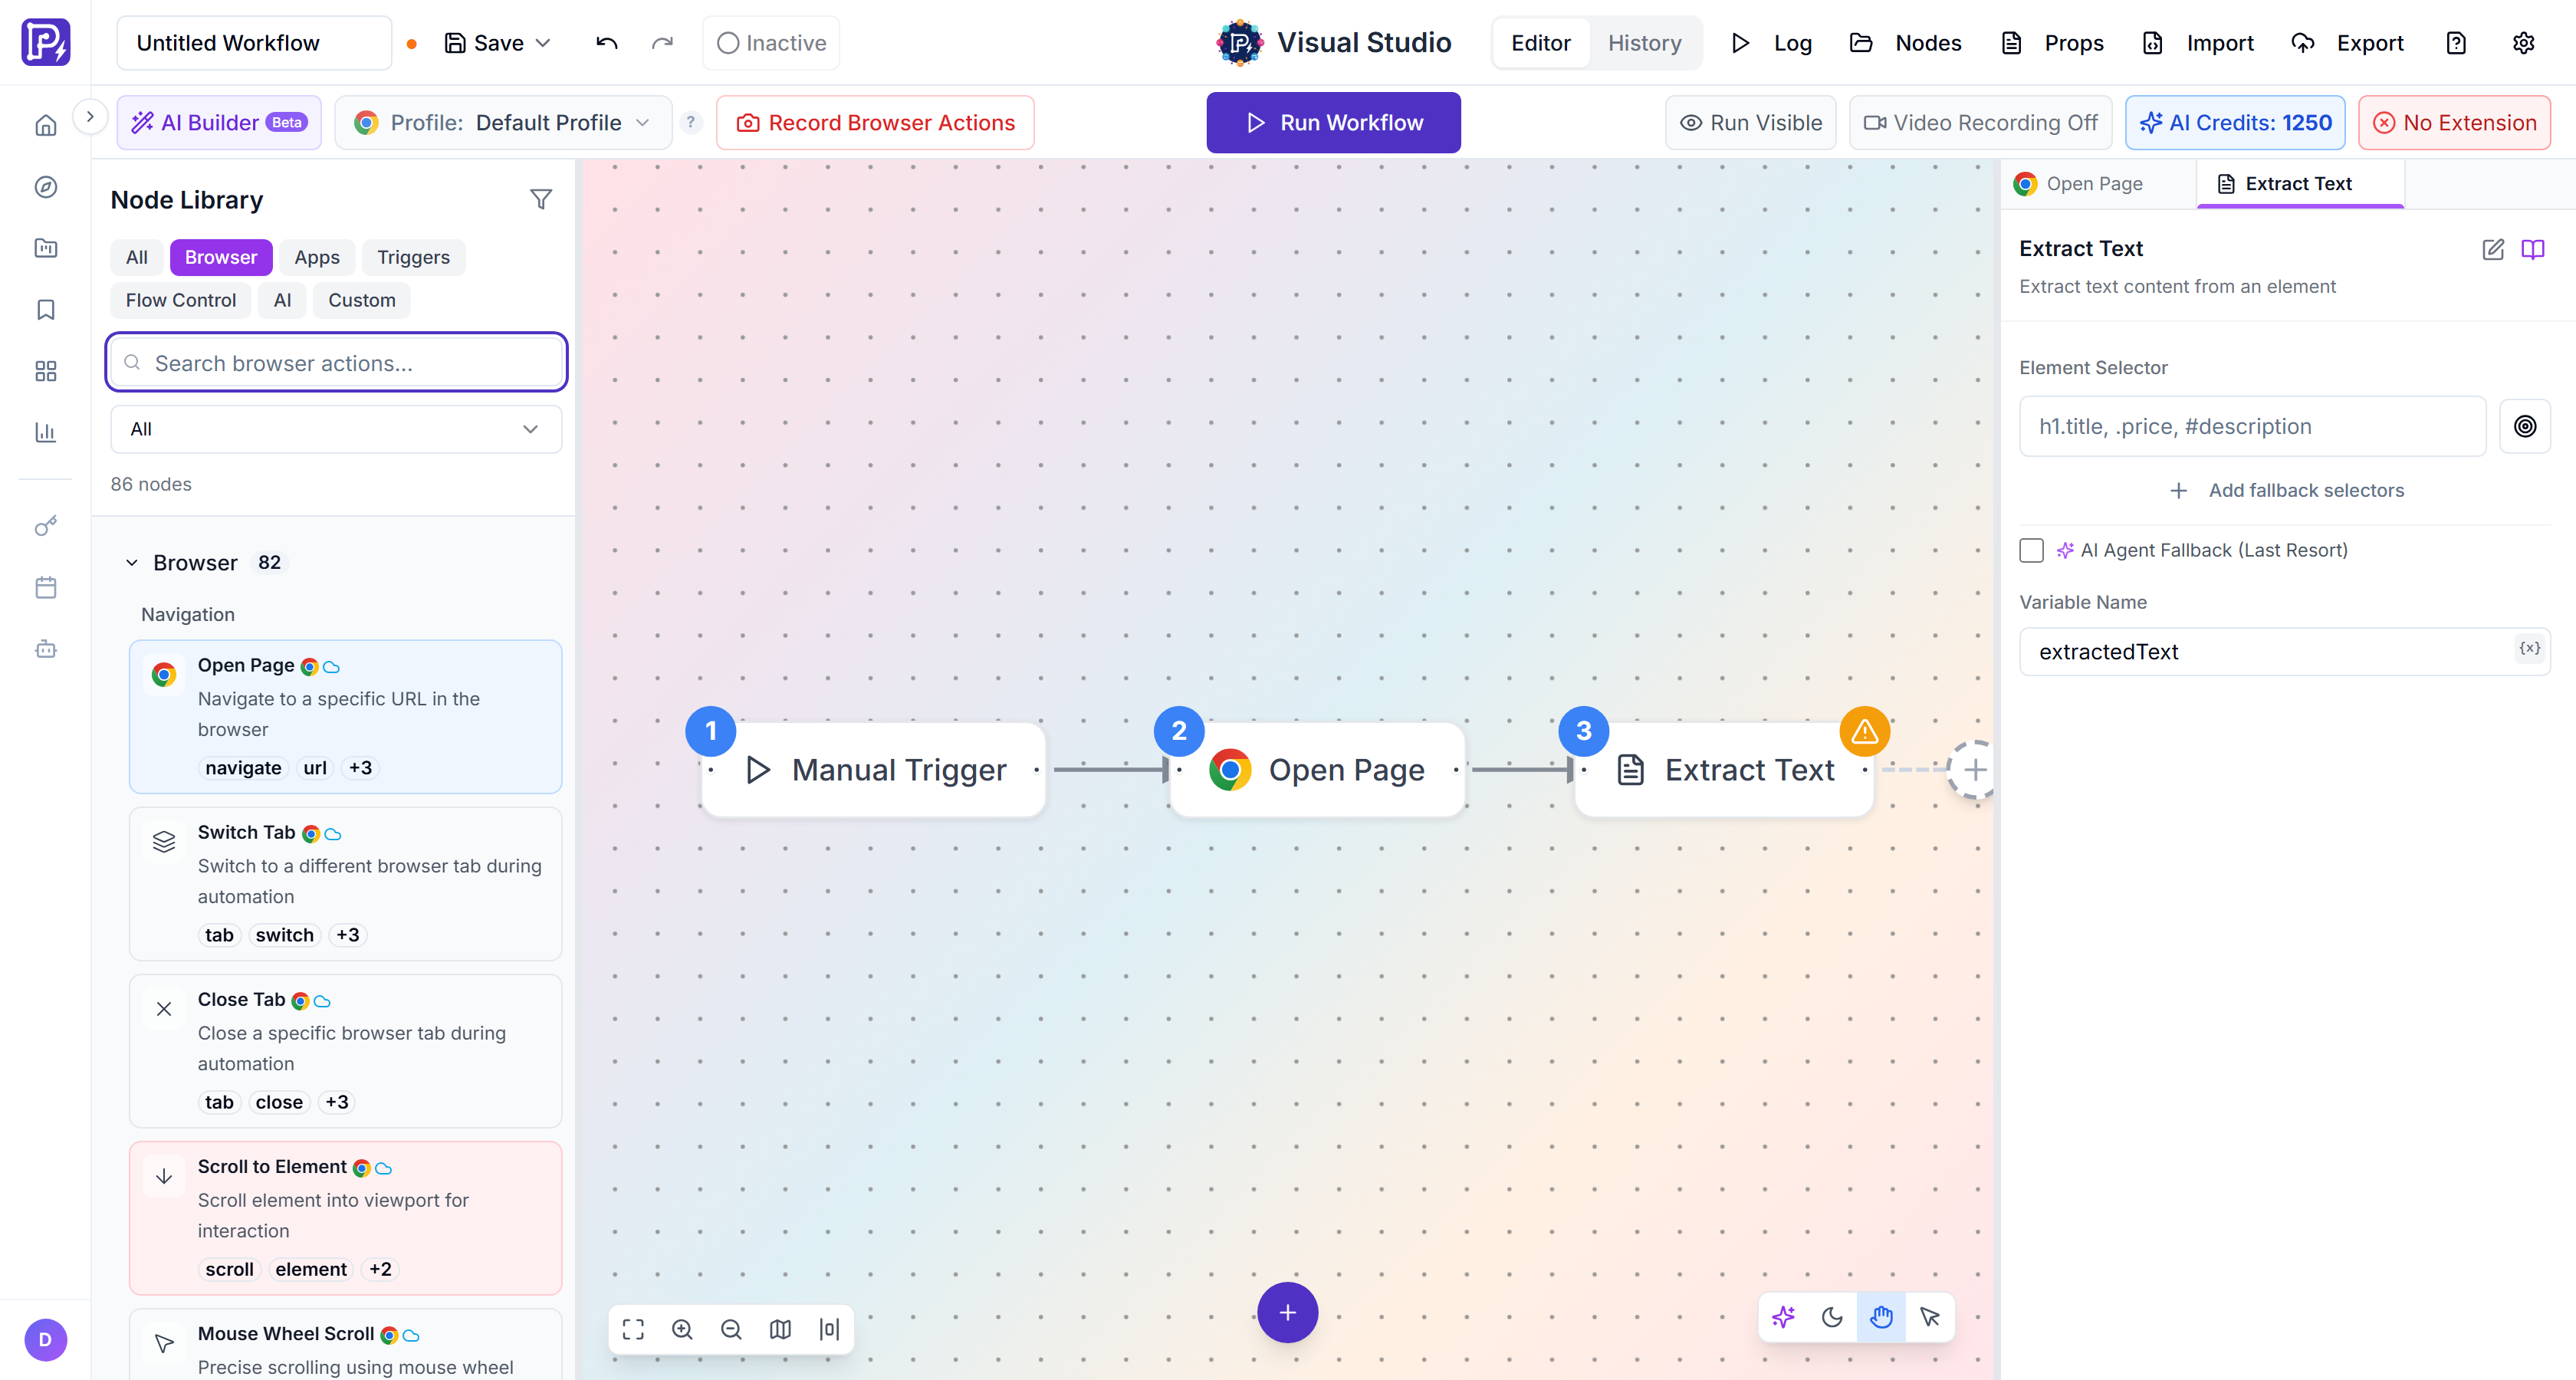
Navigate to the target URL in cloud Chromium (or your own local Chrome) so JavaScript, cookies and logins behave exactly like a human visit.
Use the automatic selector picker to click the data you want. Prompteryx stores several ranked selectors per element so the scraper self-heals when the layout changes.
Pull repeating items (cards, table rows, listings) into clean fields — text, attributes, links — with pagination handled in the loop.
Append to Google Sheets, push to Airtable, post to Slack, or call any of 3,000+ apps — no extra glue code.
Flip the workflow to Active and it runs on the server on your cadence. Each run is recorded as video with a full step-by-step log.
Start from a working workflow
Web Data Scraper
Navigate, extract repeating rows, and append straight to Google Sheets. Works on any site because it drives a real browser.
Extract Data from Web Pages
A deeper toolkit: extract text, HTML and attributes, count elements, and run custom JavaScript for advanced extraction.
See it in Prompteryx
Why Prompteryx for this
Smart selectors with AI fallback
Every element is captured with multiple ranked selectors. If the site changes and the primary breaks, the next candidate runs automatically — only if all of them fail does an AI agent step in to locate it visually.
Full video recording
Every run is captured end to end. When data looks wrong, watch exactly what the browser saw instead of debugging blind.
Scheduled, server-side runs
Set a cadence and the scrape runs on our servers — your laptop can be closed. n8n-style cron without wiring your own infrastructure.
Login & local-Chrome scraping
Need data behind your account? Run on your own local Chrome with your existing sessions, or use persistent cloud profiles.
Real-life examples
Scrape a paginated business directory every night and append new listings to a shared Google Sheet, deduped by URL.
Walk a marketplace category, capture title, price, rating and stock for each product, and export a clean CSV for analysis.
Log into a SaaS dashboard with your real Chrome session and export a report that the vendor offers no API for.
Frequently asked questions
Do I need to write code to build a scraper?
No. You build scrapers on a visual canvas, or record yourself performing the actions once and convert the recording into a reusable workflow. Code nodes are available if you want them, but they're optional.
What happens when the website changes its layout?
Each element is stored with several ranked selectors. If the primary selector breaks, Prompteryx automatically tries the next candidate, and only falls back to an AI agent if every selector fails — so most layout changes never break your scraper at all.
Can it scrape sites that require a login?
Yes. Use a persistent cloud profile to keep a session, or run on your own local Chrome with your existing logins so the scraper sees exactly what you see.
How is this cheaper than running my own browsers?
Cloud browser time is billed by the second, not rounded up to the minute, so short scheduled checks cost a fraction of what whole-minute pricing charges. There's nothing to host or keep patched.